Distributional RL With C51 and QR-DQN Compared
Two opposite designs for learning return distributions each have different strengths.
- Written by
- Desmond Fong-Whitaker
- Published
- November 4, 2026
- Reading time
- 8 min read
- Sources cited
- 7 sources ↓
What this covers
C51 and QR-DQN approach distributional reinforcement learning from opposite ends. C51 fixes return locations and learns their probabilities, while QR-DQN fixes quantile fractions and learns return locations. Neither is uniformly superior, because the benefit of each design depends on the surrounding system and the policy objective.
Why standard Q-learning discards information that matters
Standard DQN reduces the distribution of future returns to one expected value. The mean leaves out shape, spread, and tails. A tightly clustered return and a highly variable return can therefore produce the same estimate, even though their consequences for learning stability and policy quality differ. Bellemare, Dabney, and Munos argued that the value distribution, rather than only its expectation, should be central to what the agent learns.
Distributional RL restores that information by modeling the return distribution. This gives learning a richer target than a scalar, although it does not by itself require the policy to optimize anything other than expected return. The representation is the decisive design choice. C51 and QR-DQN make that choice in opposite ways, fixing the quantities that the other algorithm learns.
The structural inversion at the heart of C51 and QR-DQN
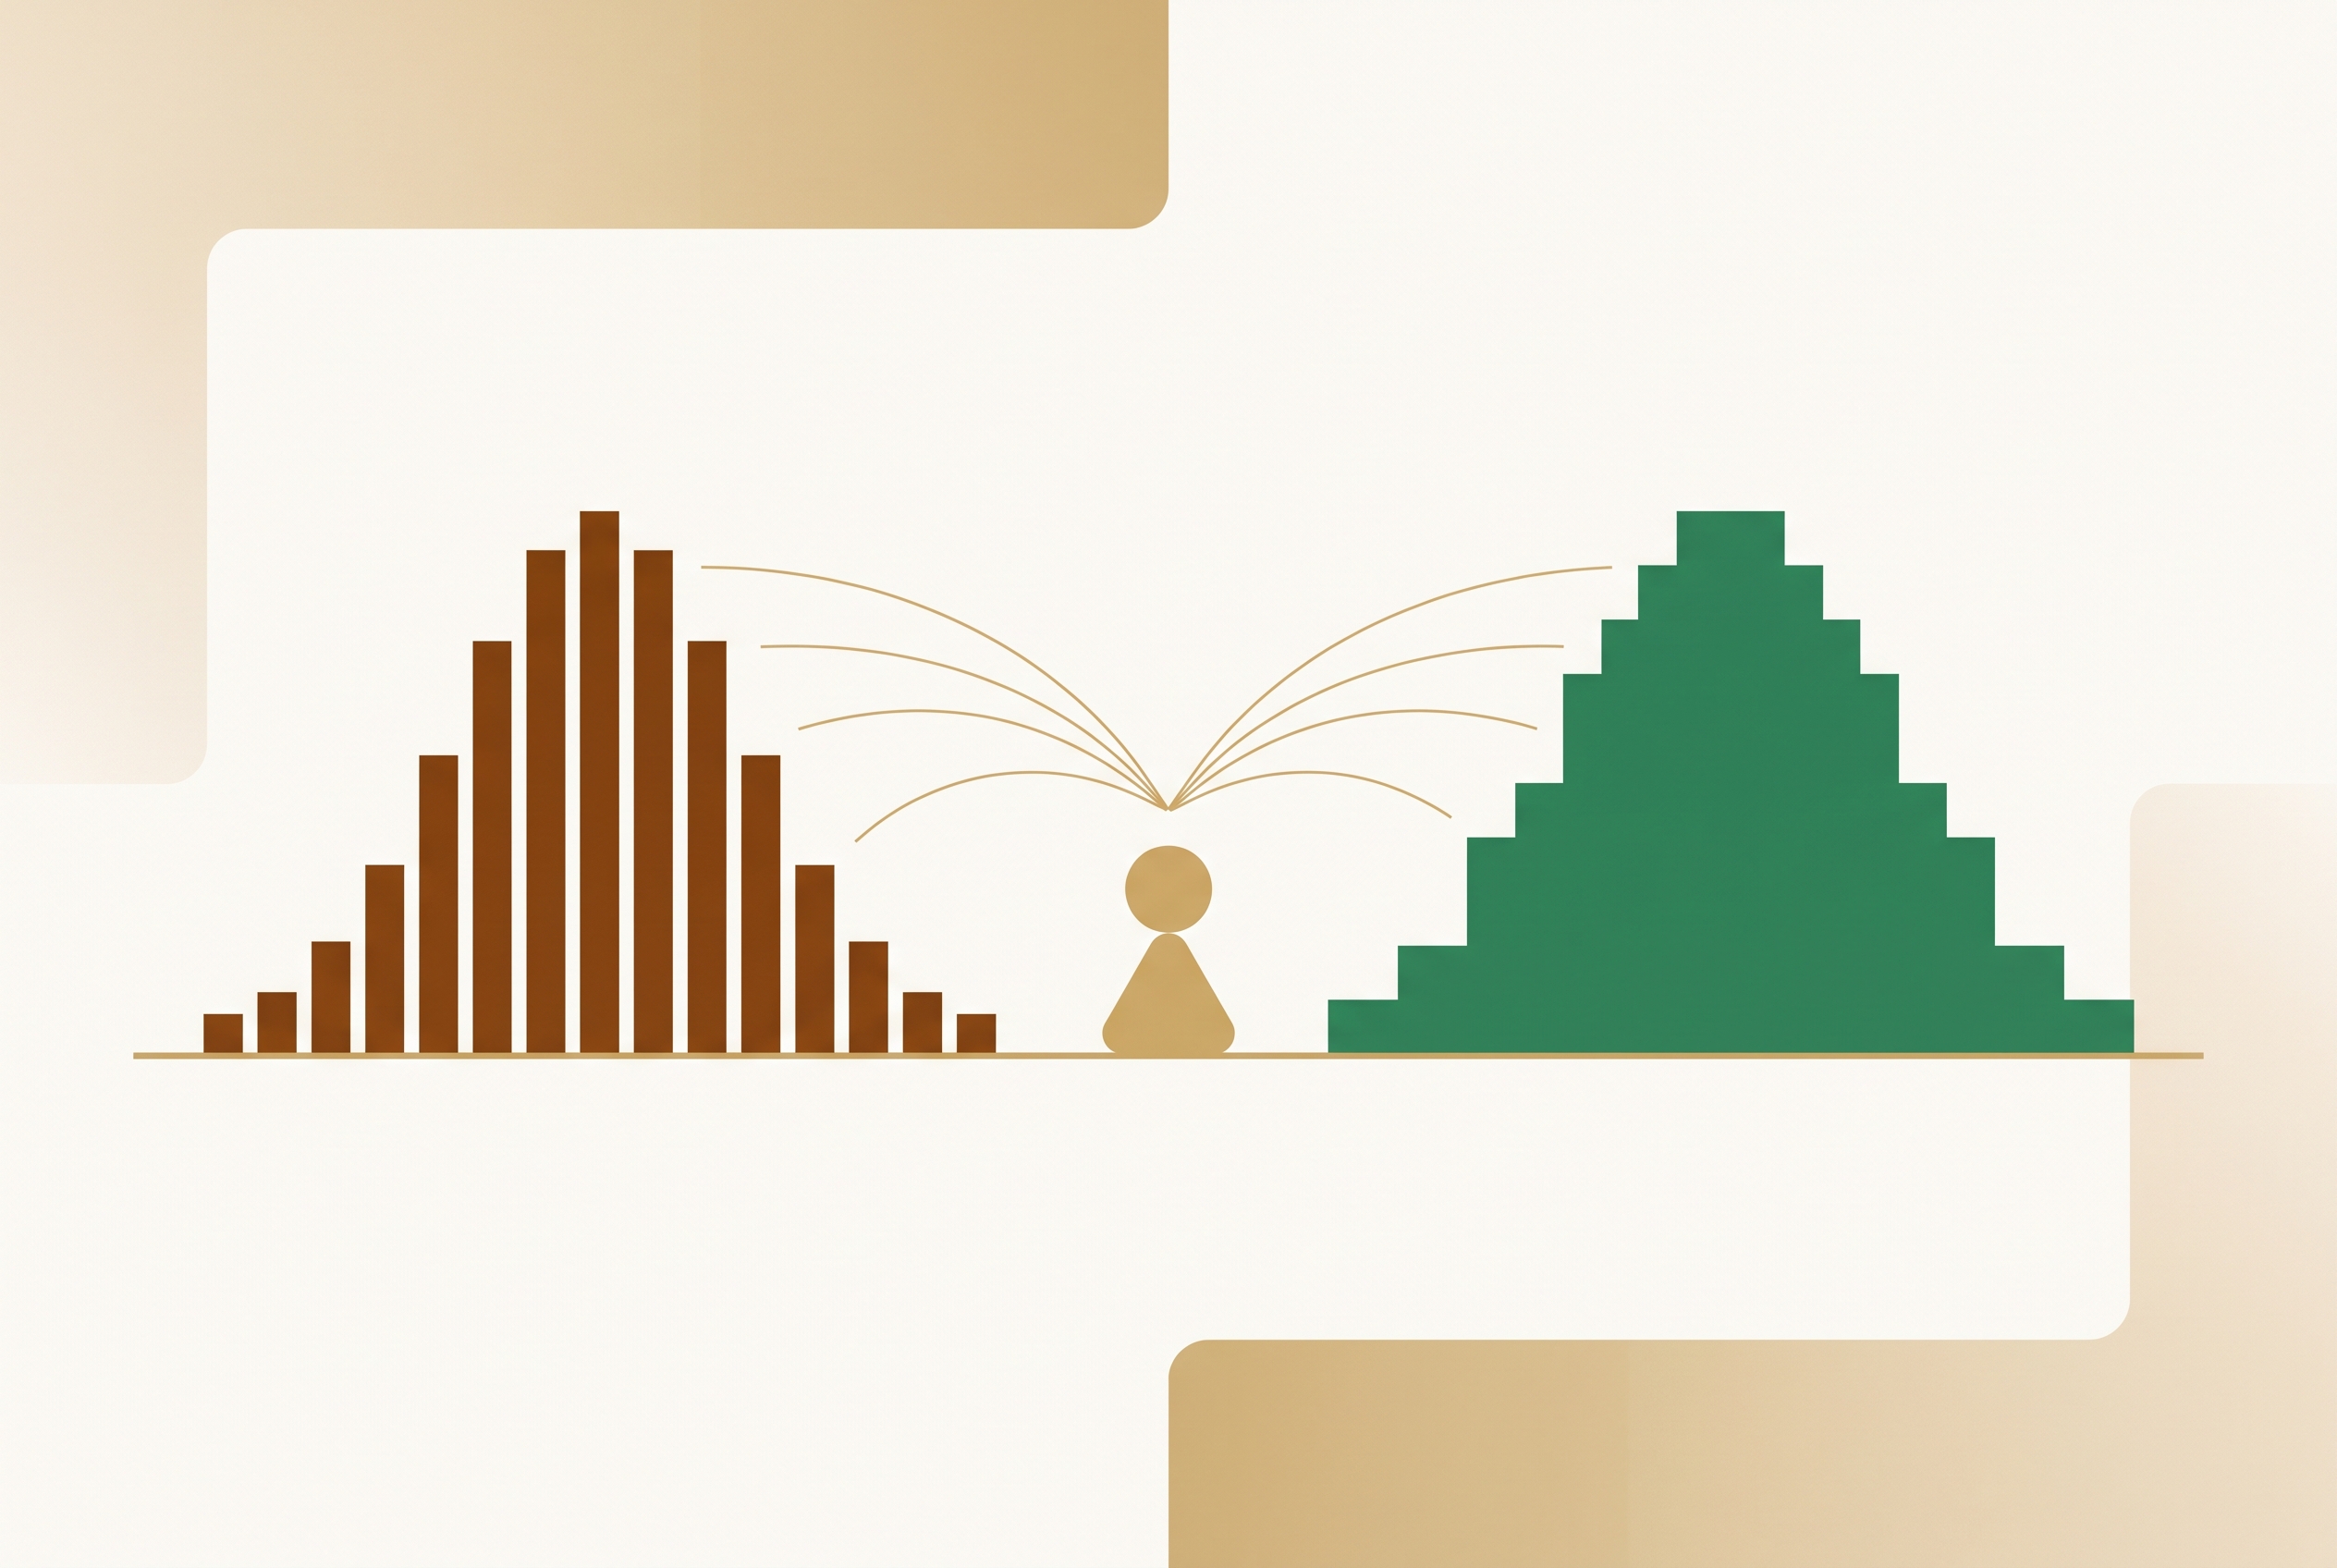
C51 uses fixed support and learned probabilities, while QR-DQN uses fixed probabilities and learned support. In C51, the support is a uniformly spaced “comb” of return values between prespecified bounds, Vmin and Vmax. The network produces logits for each action, and a softmax converts them into probability weights over those atoms.
QR-DQN instead predicts N quantile values per action. Each value corresponds to a fixed quantile fraction, given by τᵢ = (i−0.5)/N, but its return location is learned. The locations can move as the return distribution changes. Both algorithms retain the DQN backbone, including a replay buffer, a target network, and an ε-greedy policy, so the comparison concerns the distributional representation rather than a replacement of the surrounding infrastructure. Even this small change in the architecture affects projection, optimization, and the kinds of approximation error each method makes.
How each algorithm's projection and loss function follows from its parameterization
C51’s Bellman update produces a target distribution whose locations need not coincide with its fixed atoms. The target must return to the grid. Its categorical projection distributes probability mass to neighboring atoms in proportion to distance, using triangle kernels, and clips returns outside the support bounds. C51 then minimizes cross-entropy between the projected target and its predicted probabilities, equivalent to minimizing KL divergence for that fixed target. The loss fits the softmax output, but it checks agreement with a target that projection has already changed.
QR-DQN avoids that explicit remapping onto a fixed grid. For a sampled transition, each target quantile is the reward plus the discounted target-network quantile for the next action that is chosen. That action maximizes the mean of the target quantiles. The quantile Huber loss then compares current and target quantile values, penalizing errors asymmetrically according to the quantile fraction and the side of the target on which the prediction falls. Its Huber form stabilizes optimization relative to the strict quantile loss.
The metric alignment gap that separates their theoretical guarantees
Distributional Bellman contraction theory uses Wasserstein distance, while C51 trains through KL divergence after projection. Bellemare, Dabney, and Munos’s 2017 work acknowledged this theory-practice gap, which does not invalidate C51’s empirical success but limits how directly its training objective follows from the contraction argument. Metric alignment should also not be read as an unconditional convergence guarantee for the complete deep control algorithm.
QR-DQN brings the objective closer to that theory. Quantile regression approximates Wasserstein distance, and the learned locations can adapt without a fixed-support remapping step. C51, by contrast, uses a Cramér-minimizing projection whose mean-preserving redistribution within the support can overestimate variance. The IQN paper identifies flexibility in support location as a reason QR-DQN improves on C51’s Atari performance, where the fixed-support approximation introduces systematic error. The distinction is therefore a design tension with measurable consequences.
What the fixed-support constraint costs C51 in practice
C51 requires bounds that fit the return range of the domain. When returns fall outside the interval, clipping removes information about their extremes and misrepresents the distribution near its boundaries. A wider interval avoids some clipping, but if the true distribution fills only a narrow part of it, atoms elsewhere use up capacity without making the estimate more accurate. The practitioner must therefore supply domain knowledge before learning can allocate probability effectively.
Even suitable bounds do not eliminate grid error. When a target falls between atoms, the projection spreads its mass across neighboring locations. The resulting distribution can be broader than the true one. The 2025 NFDRL paper identifies this broadening as a specific categorical limitation, distinct from the limitations of quantile-based methods. QR-DQN avoids the need to set bounds entirely because its learned support is not confined to a prespecified interval.
What QR-DQN gains by freeing the support — and what it costs
QR-DQN does not require advance knowledge of return bounds. Its locations follow the distribution being learned. This removes the categorical clipping constraint and makes its quantile approximation more tractable than C51’s explicit projection onto fixed atoms. The freedom is nevertheless incomplete, because QR-DQN still represents the distribution as a sum of Dirac masses at fixed quantile fractions. The NFDRL paper identifies the resulting lack of control over local spread between quantiles as a separate representational limitation.
The computational cost also grows with resolution. Each forward pass gives N outputs for each action, and the loss adds up all N² pairs of current and target quantiles. More quantiles therefore need more computation and memory, and large action spaces multiply the number of outputs needed. Continuous action domains present a further scaling challenge for this per-action architecture.
Empirical performance on Atari-57 and what the scores actually show
The IQN paper reports a mean human-normalized score of 864% for QR-DQN on Atari-57. C51 trails substantially on the mean, but the median gap is much smaller. This pattern suggests that QR-DQN’s advantage is concentrated in high-scoring games. It supports a performance benefit from the more flexible representation without establishing uniform dominance.
The FQF paper likewise places QR-DQN ahead of C51 on both mean and median score. Its median results agree with the IQN comparison, while mean scores change with the evaluation protocol. Both papers retain the ordering from DQN to C51 to QR-DQN. Yet C51’s gains over DQN were already dramatic on many Atari games, whereas QR-DQN’s additional gain is more incremental at the median.
Why the theoretical advantage of QR-DQN shrinks inside Rainbow and composite systems
Rainbow complicates the standalone comparison because its distributional component operates with other improvements. Rainbow was originally evaluated only with C51, so the established contribution of that component initially concerned the categorical parameterization. A study that replaced C51 with QR-DQN in a Rainbow-style system found no significant difference. The pairwise ranking did not transfer cleanly. Interactions among prioritized replay, multi-step returns, and noisy nets can affect performance more than the choice between distributional representations.
A fast-training Rainbow study found that removing distributional RL had no significant effect on final performance or learning speed over a shorter horizon, and that its main benefit appeared only after much longer training. The study’s authors excluded it from their final agent because the improvement was negligible relative to implementation complexity. “Revisiting Rainbow” also found that adding distributional RL alone to DQN could hurt performance on some games.
How the choice of parameterization affects risk-sensitive applications
Risk-sensitive policies use parts of the return distribution that the mean conceals. QR-DQN makes those parts more directly accessible. Because it represents quantiles directly, it supports lower-tail objectives such as CVaR and upper-quantile objectives for optimistic exploration, while C51 requires tails to be calculated from probabilities at fixed atoms. IQN exhibits a monotone risk-aversion ordering when maximizing CVaR, whereas C51 shows only partial ordering with irregularities and QR-DQN does not show the same predictable ordering.
Hêche et al.’s 2025 study applied C51, QR-DQN, and IQN to real natural gas futures trading data from Predictive Layer SA. The study found that distributional RL significantly outperformed classical RL methods, with C51 achieving an improvement of more than 32%. C51 was therefore effective despite its less direct tail representation. The same study cautioned that QR-DQN’s risk-sensitive variants should not be assumed to respond to the CVaR confidence level as expected.
Locomotion illustrates a different consequence of the representation. A C51-style agent controlled a biped robot that played soccer without risk-sensitive learning. The subsequent RALL system achieved the first risk-sensitive locomotion policy via a distributional value function, using the interquartile range of a quantile distribution to represent environmental risk. That formulation required a change from C51’s categorical representation to a quantile-based one.
Where both algorithms remain structurally limited and what comes after them
C51 assigns probabilities to fixed atoms, while QR-DQN places Dirac masses at learned locations associated with fixed quantile fractions. Neither representation offers unrestricted control over distributional shape. Complex or unbounded return distributions reveal different limits in each, even though QR-DQN has none of C51’s numerical bounds. Continuous control and unbounded support remain frontiers for IQN, FQF, and flow-based approaches.
The NFDRL paper proposes normalizing flows that model return distributions as continuous, unbounded densities. Both of its variants achieved performance competitive with the DQN, C51, and IQN baselines, rather than establishing that those baselines had been displaced. The 2025 ADDQ paper takes a complementary path by adding adaptive distributional double Q-learning to existing C51 code with changes to just a few lines. C51 remains a foundation for further development. New representations and extensions of established ones are advancing in parallel.
For practitioners, the binding constraint determines the choice. C51 is simpler to implement, has a softmax regularization effect, and fits naturally within Rainbow-style pipelines, but it requires bounds to be chosen and comes with fixed-grid distortion. QR-DQN offers closer metric alignment, learned support without prescribed bounds, and a more direct basis for risk-sensitive objectives, at higher computational cost and without guaranteed gains in composite systems or predictable risk ordering. The structural inversion makes that trade-off explicit, with one design learning how much probability belongs at fixed returns and the other learning where fixed probability fractions belong.
Methodology & sources
- Implicit Quantile Networks for Distributional Reinforcement Learning
Cited directly as the IQN paper identifying fixed-support approximation error as a reason QR-DQN improves on C51's Atari performance.
- On the Importance of Exploration for Generalization in Reinforcement Learning
Cited as a fast-training Rainbow study finding that removing distributional RL had no significant effect on performance over shorter training horizons.
- ADDQ: Adaptive Distributional Double Q-Learning
Referenced as the 2025 ADDQ paper describing an adaptive distributional double Q-learning extension that modifies existing C51 code with minimal changes.
- Fully Parameterized Quantile Function for Distributional Reinforcement Learning
Referenced as the FQF paper placing QR-DQN ahead of C51 on both mean and median Atari score.
- A Comparative Analysis of Expected and Distributional ...
Provides the comparative analysis of expected and distributional RL methods used to support claims about performance ordering and risk-sensitive behavior.
- Distributional Reinforcement Learning with Quantile Regression Will Dabney
Source for QR-DQN's quantile Huber loss formulation, fixed quantile fractions, and Atari benchmark results cited in the article.
- Implicit Quantile Networks for Distributional Reinforcement Learning
The IQN paper reporting a mean human-normalized score of 864% for QR-DQN on Atari-57 and discussing risk-sensitive CVaR ordering across distributional methods.