Policy Gradient Variance Reduction Techniques for Sparse Reward Environments
Practical techniques that tame gradient noise when rewards are scarce and rollouts are few.
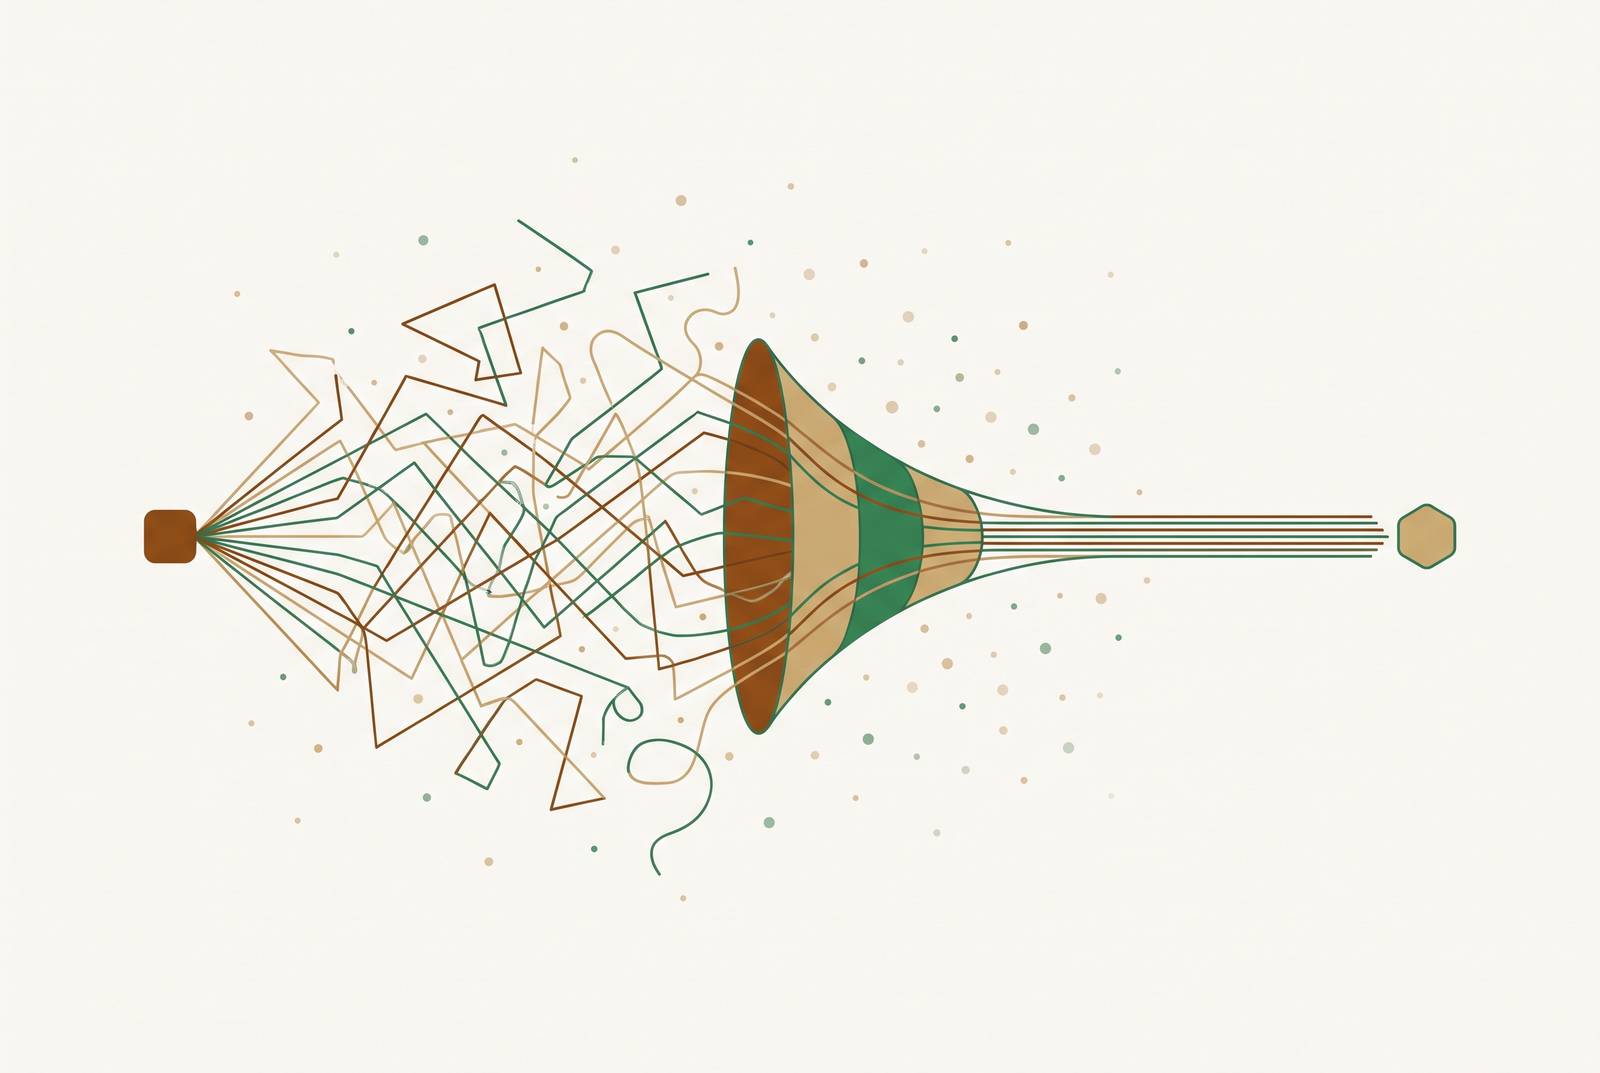
Sparse rewards don't just make reinforcement learning harder, they make the underlying math of policy gradient methods unreliable in a specific, measurable way: variance in the gradient estimate balloons, and the agent spends most of its training signal on noise instead of learning. This piece walks through why that happens and lays out the toolkit that practitioners actually reach for to fix it, from baseline subtraction to shrinkage estimators to reward profiling to credit assignment schemes built for language models and multi-agent systems alike. Each technique attacks variance from a different angle, and knowing which lever to pull, and when, is most of the job.
Why sparse rewards worsen the policy gradient variance problem
Policy gradient methods give you an unbiased estimate of the gradient, which sounds like a good deal until you notice the fine print: unbiased doesn't mean low-variance. Under dense rewards, where the environment hands back a useful signal on nearly every step, the variance is annoying but tolerable. Under sparse rewards, it turns into something closer to catastrophic.
Most real environments don't hand you dense, well-shaped rewards. A robot arm either grasps the object or it doesn't. A robot arm either grasps the object or it doesn't, and a code-generation model either passes the test suite or it doesn't. The common case is a binary success-or-failure signal that appears rarely and tells you nothing about the steps leading up to it. Model-based RL, which normally earns its keep by planning ahead using a learned model of the world, loses that advantage here too: if the reward signal is too sparse to shape the planner's search, the model has nothing to plan toward.
Mechanically, here's what happens. When the overwhelming majority of trajectories return zero, the handful that do return something nonzero end up dominating the gradient estimate, and they do it through sheer statistical noise rather than signal. Fit a reward model to ground-truth scalar values in this setting and you can end up with a model that's technically accurate and still useless: it predicts zero almost everywhere, so the gradient of that reward model is zero almost everywhere too. That's a flat landscape with no hills to climb, even though the reward model "works." REINFORCE, the original policy gradient algorithm, is especially exposed to this: its update depends on total returns that swing wildly between one stochastic rollout and the next, and averaging over those swings is what slows convergence to a crawl.
None of this is a tuning problem you can patch by adjusting a learning rate. Exploration failures (the agent never stumbles onto the reward in the first place) and credit assignment failures (the agent can't tell which of its actions caused the reward it did get) are tangled up with variance, not separate from it. Fix the variance without fixing exploration or credit assignment, and the agent still gets stuck.
How baselines reduce variance without introducing bias
The oldest fix in the book is the baseline: subtract some reference value from the return before you compute the policy gradient. Done correctly, this leaves the gradient estimate unbiased (the math works out so the subtraction cancels in expectation) while cutting its variance substantially. That's the whole trick, and it's a genuinely elegant one.
Statisticians would recognize this as a control variate, and RL uses two main flavors of it: additive baselines, which subtract a value that doesn't depend on the action taken, and action-dependent critics, which do. There's a mathematically optimal baseline you can derive for a given problem, and the penalty for using a worse one isn't arbitrary. It comes out as a weighted squared distance between the baseline you picked and the optimal one, so the further off you are, the more variance you're carrying around unnecessarily.
Where you land on that spectrum matters a lot in practice. A constant baseline is the simplest option, and it tends to underperform more adaptive choices in highly non-stationary environments, which sparse-reward settings usually are. A state-dependent value function is the standard choice, and for good reason: it's the backbone of every actor-critic method in wide use today. Pushing further gets you an action-dependent critic, which cuts variance more but introduces bias unless it meets strict compatibility conditions with the policy. Those conditions are rarely satisfied once you're using stochastic gradient descent and deep neural networks for function approximation, which is to say: almost always, in modern practice.
In environments where an outside, exogenous random input drives the dynamics, the state alone doesn't carry enough information to predict expected future returns. Queuing systems, robotics under disturbances, object tracking under sensor noise, that kind of thing. In these settings the state alone doesn't carry enough information to predict expected future returns, so a plain state-dependent baseline underperforms. Mao and colleagues at MIT CSAIL derived a bias-free, input-dependent baseline for exactly this case, and it outperforms the standard state-dependent version when the input process is the thing actually driving outcomes.
Critic-free baselines for LLM post-training and the low-rollout estimation problem they create
Reinforcement learning with verifiable rewards, RLVR for short, is the technique behind a lot of recent LLM post-training, and it has turned sparse-reward variance reduction into a front-line engineering concern rather than a theoretical curiosity.
The obvious move, an actor-critic setup, is expensive here. PPO and its descendants (VC-PPO, VinePPO, VAPO) all require training a separate value model alongside the policy, and for a large language model that critic is itself a sizable, expensive network to maintain and keep synchronized with the policy.
That cost is what pushed practitioners toward critic-free baselines. RLOO uses a leave-one-out baseline: for a given prompt, sample several responses, and use the average of the others as each response's baseline. ReMax swaps in a greedy-decoded response as the reference point instead. GRPO samples a group of responses per prompt, takes the group's mean reward as the baseline, and then normalizes by the within-group standard deviation, effectively giving each response a z-scored advantage relative to its own prompt's group. DAPO builds on this with higher clipping thresholds and sequence-level losses for steadier training. GSPO replaces the sequence-level importance weight with a sequence likelihood term to avoid the high-variance noise that per-token ratios can introduce. CISPO and Dr.GRPO round out the family, the latter specifically targeting bias issues that occur in vanilla GRPO.
All of these share a structural weakness. RLVR training typically runs with large batch sizes but very few rollouts per prompt, sometimes as few as two or four, because inference on a large language model is expensive and you can't afford to sample fifty completions for every prompt in the batch. Even scaled up to industrial training runs, rollout counts per prompt stay small relative to what you'd want statistically. The per-prompt empirical mean these methods use as a baseline is itself a noisy estimate of the true expected value. The variance-reduction tool has picked up a variance problem of its own. RLOO and GRPO both perform well once rollout counts climb high enough for the per-prompt average to be trustworthy, but in the low-rollout regime where RLVR training actually happens, that assumption doesn't hold.
Shrinkage baselines: borrowing strength across prompts to stabilize low-rollout gradient estimates
Zeng, Zhou, Arora, and Zanette, working out of Carnegie Mellon, propose a fix rooted in a decades-old statistical result. Their paper, "Shrinking the Variance: Shrinkage Baselines for Reinforcement Learning with Verifiable Rewards" (arXiv:2511.03710), is set to appear at ICML 2026.
The underlying idea traces back to Stein's paradox: when you're estimating several group means at once (three or more), using each group's own sample mean as your estimate is provably not the best you can do. A shrinkage estimator, one that pulls each group's estimate partway toward the shared, overall mean, achieves strictly lower mean squared error across the board. It sounds almost too convenient, a free lunch in statistics, but it's a well-established result, not a heuristic.
Applied to RLVR, the James-Stein (JS) baseline blends the per-prompt reward mean with the across-prompt reward mean, which sharpens the accuracy of the per-prompt value estimate precisely in the low-rollout regime where a lone per-prompt average is shakiest. The paper's guarantee is the useful part for practitioners: the shrinkage baseline provably produces a lower-variance policy gradient estimator across the algorithms it's tested against, and even though the shrinkage introduces a small amount of bias into the baseline itself, that bias doesn't propagate into the policy gradient estimator, which stays unbiased. You get the variance reduction without paying for it in correctness.
Reward profiling: gating policy updates to prevent catastrophic collapses without algorithm-specific tuning
A separate line of work, from Ahmed, Bergou, Dutta, and Wang (arXiv:2511.16629, submitted November 2025 and revised the following January), takes aim at a different failure mode: not noisy gradients exactly, but policy updates that look fine on paper and then collapse training in practice.
Existing fixes for this, baseline normalization, trust-region constraints of the sort PPO uses, all work to a degree, but each comes with its own tax. Trust regions often mean second-order solvers or extra tuning specific to the algorithm you're running, and that cost compounds when you're trying to standardize training across multiple model families or reward setups.
Reward profiling is built as a wrapper instead, something you can bolt onto any policy gradient algorithm without rewriting its internals. After the algorithm computes a candidate update, the framework spends a small number of additional rollouts checking that update against the current policy's estimated return before committing to it. It has three response modes: accept the update outright (the paper calls this Lookback), blend the candidate update with the current policy (Mix-up), or step to a midpoint between the two (Three-Points). The latter two exist specifically so the method doesn't get too conservative and lock the agent into a local optimum while it's busy protecting itself from a bad update. If the new policy doesn't show a high-confidence improvement over the old one, the update gets rejected or blended down rather than applied wholesale.
Reward profiling doesn't slow down the convergence rate of whatever policy gradient method it's wrapping, and with high probability it produces performance improvements that are stable and monotonic instead of the up-and-down instability sparse-reward training is prone to; this theoretical result is what makes it worth adopting rather than just an engineering convenience.
Token-level credit assignment as a structural fix for sparse sequence rewards
Baselines and gating both work on the variance of the gradient estimate. A different family of fixes goes after a related but distinct problem: how credit for a reward gets distributed across the decisions that led to it.
Sequence-level RL, the traditional setup for training language models with RL, assigns one scalar reward to an entire generated response and then spreads that signal evenly across every token in the sequence. That's a coarse approximation. If only a handful of tokens actually determined whether the response passed or failed (the line where a proof goes wrong, the function call that's malformed), spreading the same credit across every other token in the sequence buries the useful signal in noise.
Token-level policy gradient methods reframe the generation process as a Markov decision process at the token level: each token is a state, each next-token choice is an action, and the reward, arriving either as a single terminal signal or from a token-level reward model, gets converted into a per-token advantage rather than one blanket number for the whole sequence. Clipping, entropy regularization, and geometric-mean weighting schemes are layered on top to keep this stable.
Several algorithms fall into this family, each with a different way of handling the token-level ratio. GRPO gives every token in a sequence the same normalized group advantage. GSPO (from Zheng and colleagues) and TEPO (from Lin and colleagues) instead compute one importance ratio for the whole sequence and share it geometrically across tokens, which sidesteps the high-variance noise that comes from tracking a separate ratio per token. ETPO applies a per-token soft Bellman update with entropy regularization injected at each step. GTPO extends this line of per-token methods with additional regularization. Across this literature, the reported effect is consistent: token-level credit assignment improves accuracy on reasoning, tool-use, and code-generation tasks compared to sequence-level baselines.
Multi-agent credit assignment: difference rewards as a variance-reduction tool in cooperative settings
Multi-agent RL adds a wrinkle sparse-reward research in single-agent settings doesn't have to deal with: even when the reward signal is generous, a shared reward tells each agent nothing about how much of that outcome its own actions were responsible for. Naive policy gradients trained on a shared signal can converge to sub-optimal joint policies, because each agent is essentially guessing at its own contribution.
Difference rewards solve this by reshaping what each agent learns from. Instead of the raw shared reward, an agent gets a signal built to isolate its own marginal contribution to the group outcome, and it can do this without needing full centralized information at execution time.
Dr.Reinforce combines this idea with policy gradients directly, training decentralized policies in settings where the reward function is known ahead of time. It skips learning a Q-function altogether, which sets it apart from COMA (counterfactual multi-agent policy gradients), a method that computes its counterfactual baseline through a learned action-value function and, in doing so, inherits the usual headaches of bootstrapping and a constantly shifting target. Dr.ReinforceR extends the approach to cases where the reward function itself isn't known, learning a reward network to estimate the difference rewards instead of assuming they're given.
The problem classes this shows up in are the ones where cooperative behavior matters and rewards are naturally sparse and delayed: air traffic management, packet routing across sensor networks, coordinating traffic lights across an intersection network. In each case, dozens of agents share an outcome that any one of them only partially controls, which is exactly the setting difference rewards were built for.
Intrinsic rewards and curiosity-driven exploration: attacking variance at its source rather than managing it statistically
Every technique covered so far treats sparse reward as a fixed condition of the environment and works to manage its statistical consequences, whether through better baselines, gated updates, or finer-grained credit assignment. Intrinsic reward methods take a different stance entirely: rather than making peace with a sparse signal, they add a second, denser reward stream generated by the agent itself, one that rewards novelty or prediction error rather than task success. An agent driven by curiosity picks up a training signal on nearly every step, whether or not the true task reward ever fires, which shrinks the fraction of trajectories carrying zero reward and, by extension, shrinks variance before any baseline or gating mechanism even needs to get involved.
That's a meaningfully different strategy than anything else in this toolkit, because it changes the reward landscape itself instead of processing a noisy signal more cleverly after the fact. Whether it's the right tool for a given problem depends on how much the environment rewards exploration for its own sake versus how much it punishes an agent for wandering off toward novelty and away from the actual objective, a tradeoff that has to be weighed case by case rather than assumed away.