Generalization vs Memorization in RL Environment Evaluation
Standard benchmarks can't distinguish whether RL agents learn tasks or memorize training data.
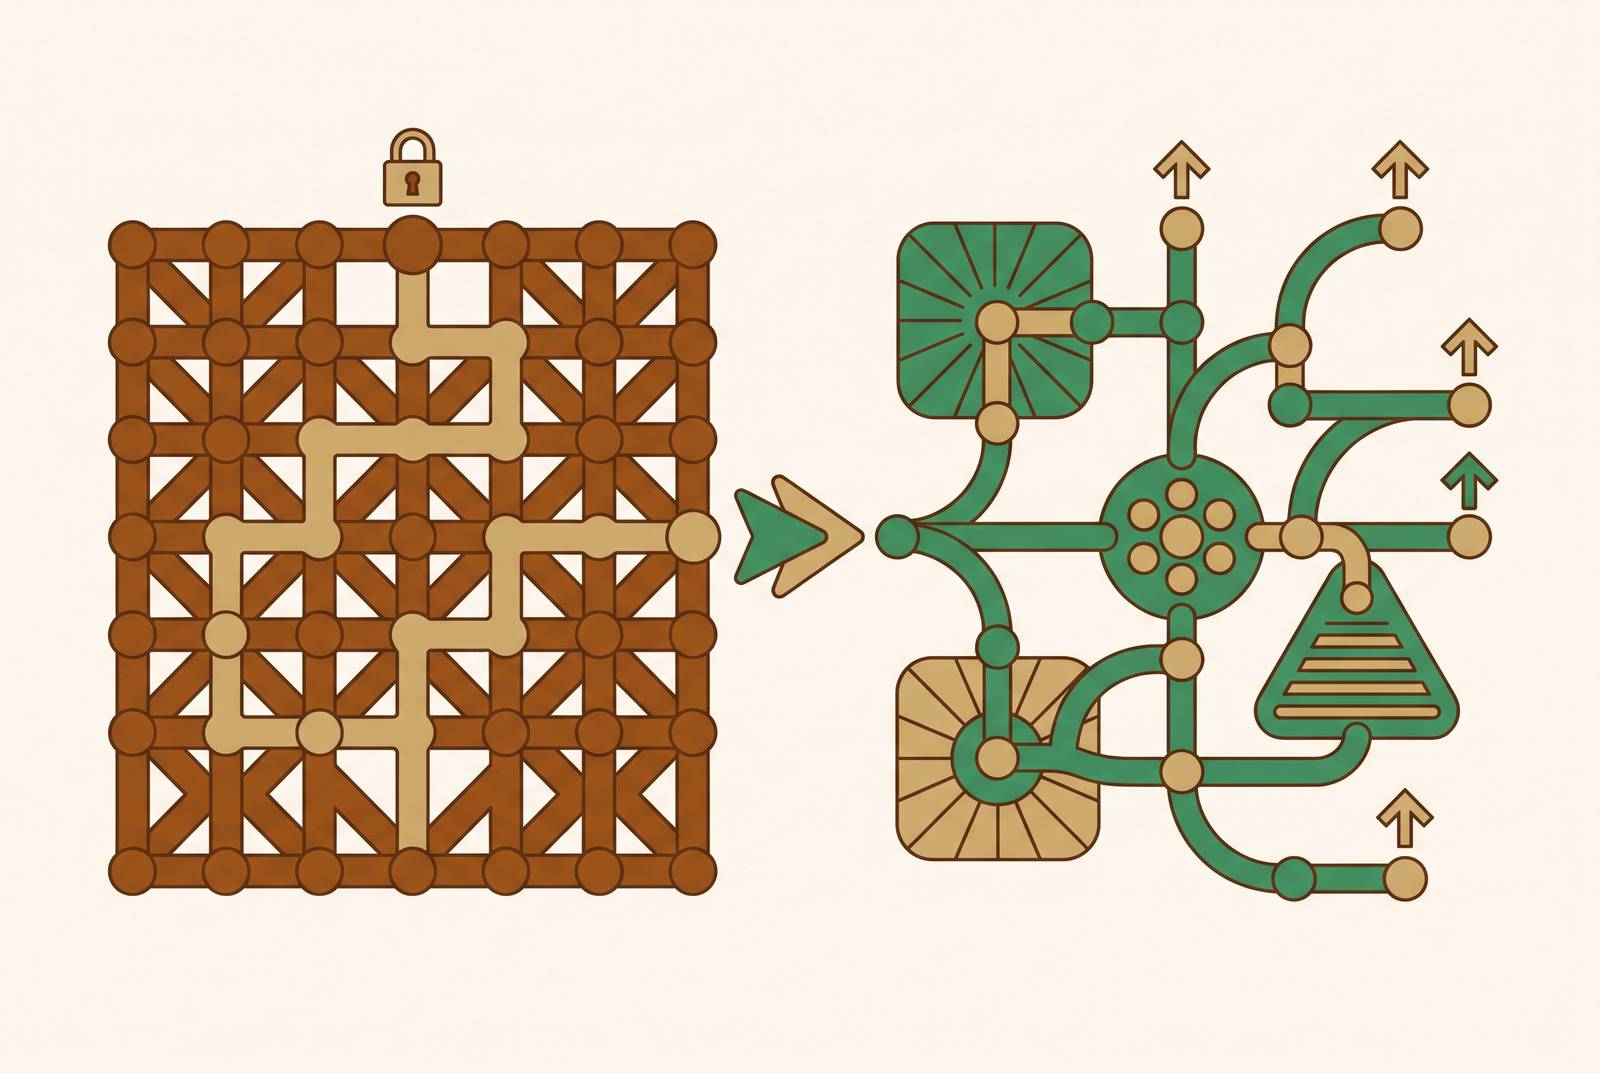
Reinforcement learning benchmarks have a measurement problem: they cannot tell you whether an agent learned how a task works or simply learned what the training data looked like. Both produce the same number on the leaderboard. The gap only opens up once you test somewhere the agent has never been, and most standard evaluation protocols never do that.
Why standard RL evaluation conflates learning with memorization
A high score on a benchmark is consistent with an agent that has extracted the actual structure of a task, transferable rules about physics, incentives, cause and effect, and it's equally consistent with an agent that has found a shortcut. It's consistent with an agent that has extracted the actual structure of a task, transferable rules about physics, incentives, cause and effect, and it's equally consistent with an agent that has found a shortcut particular to the exact levels it was trained on. Both strategies clear the same bar on a standard test, because the standard test is built from the same distribution the agent trained on.
That's the operational failure at the heart of a lot of RL research: training and testing on the same set of environments. Doing this gives you a reliable number, but the number carries almost no information about how the policy would fare against anything new. Compare this to how people handle novelty. A person who learns a platformer typically carries the underlying logic forward to new levels, because the rules transfer. RL agents trained on a fixed set of levels frequently fail on new ones outright, because they depend on surface features that differ across levels.
What memorization looks like inside an RL agent
Memorization in RL has a specific, checkable meaning: the agent is exploiting some feature that happens to correlate with reward in training, layout quirks, background art, the timing of events, rather than learning the dynamics that actually produce the reward. This is sometimes called observational overfitting, and it's a more insidious failure than it sounds, because the agent is exploiting some feature that happens to correlate with reward in training rather than being lazy. It's optimizing exactly what it was told to optimize. The correlation was just never the same thing as the task.
The clearest demonstration of this comes from experiments with Sonic in the Gym Retro environment. Saliency maps of a trained agent showed it wasn't looking at the character, the enemies, or the terrain ahead. It was attending to the timer in the top-left corner of the screen and to background objects, both of which correlated with progress during training simply because time and progress move together in a fixed level. The agent could reach a near-optimal score of 5,000 using the scoreboard timer alone as its signal, with no real understanding of platforming dynamics behind it. The dependence on the timer, rather than on platforming dynamics, was the agent's actual strategy. That single manipulation is about as clean a proof as exists that training return and generalization are separable properties, and that you can only see which one you're looking at by deliberately withholding the cue the agent depends on.
A related result comes from a maze study by Zhang and colleagues (arXiv:1804.06893), which found that agents can memorize enormous collections of randomly generated mazes. Research on maze environments has shown that agents can reach similar training performance while relying on fundamentally different internal strategies. Same training score, same architecture even, but completely different internal strategy. One learned transferable navigation principles; the other memorized the specific environments it trained on.
The epistemic POMDP and RL generalization's structural difficulty compared to supervised learning
Supervised learning has a fairly clean account of generalization: draw train and test data independently from the same distribution, measure empirical risk on training data, and hope it tracks expected risk on the true distribution. The reason that framework applies differently to RL is structural.
Ghosh, Rahme, Kumar, Zhang, Adams, and Levine work through this carefully. In RL, the agent's actions shape the observations it receives next: distributional shift isn't something that happens to the agent from outside, it's something the agent's own policy generates as it acts. And when an agent trains on a limited set of environments and is meant to generalize to new ones, something stranger happens: even a fully observed decision-making model, one where the agent can see everything relevant to the state, turns into a partially observed one at test time, because the agent has no way of knowing which such model among the plausible candidates it's currently in. Ghosh et al. call this the epistemic POMDP.
The practical sting is in what this implies about fixes borrowed from supervised learning. Standard stochastic regularization techniques (dropout, weight noise, and similar tools) are indifferent to the posterior distribution over possible MDPs the agent should be reasoning over. Policies trained this way can end up with expected test-time returns arbitrarily far below what a Bayes-optimal policy would achieve. Regularization built for i.i.d. data doesn't address the uncertainty RL agents actually face, because that uncertainty is about which world you're in, not just which sample you drew.
The consequence for benchmark design follows directly. If a benchmark never varies the underlying MDP, only its surface appearance, or doesn't vary anything at all, there is no way to tell whether an agent is reasoning under this epistemic uncertainty or simply exploiting the fixed furniture of a single environment it has seen many times. Which raises the obvious next question: how do you build a benchmark where the MDP itself is different across training and test?
CoinRun and the procedural generation turn in benchmark design
The fix is procedural generation: construct training and test sets from genuinely distinct environments, generated algorithmically rather than hand-authored and reused. This is the logic behind CoinRun, built explicitly as a benchmark for measuring generalization in RL rather than raw task performance.
The headline finding is blunt. Substantial overfitting appears in agents trained on fewer than 4,000 levels. Closing the generalization gap requires access to something like 10,000 levels. These aren't small numbers, and that's the point: overfitting in RL isn't a small-sample artifact that vanishes once you have "enough" data by ordinary standards. It persists at scales most practitioners would already call large.
What CoinRun makes visible, and what a fixed-environment benchmark hides by construction, is that training-set size alone, holding architecture and algorithm constant, controls whether an agent generalizes. That's invisible if train and test levels are identical, because there's no held-out set to fail on. The CoinRun experiments also tested standard regularization tools against this protocol: standard regularization tools each improved generalization measurably. None of that measurement would mean anything without a protocol that actually separates train from test.
Procgen Benchmark and evaluation at scale across 16 environments
CoinRun's logic scales up in the Procgen Benchmark (Cobbe et al., 2020, published via PMLR at ICML), a suite of 16 procedurally generated game-like environments built to test sample efficiency and generalization at the same time. Each environment uses procedural generation so that surface details vary across levels while the underlying game dynamics stay fixed. The agent sees a different-looking world every time but has to learn the same rules, which stay fixed while the surface details randomize.
That design decision directly targets observational overfitting. An agent cannot memorize its way through Procgen by keying on background art or fixed visual landmarks, because those change from level to level. It has to learn dynamics, because dynamics are the only thing that stays constant.
The contrast with earlier benchmarks is instructive. Gym Retro's environments are fixed, so a policy built on sequence memorization can still work, because the sequence never changes. Procgen removes that option by construction. Earlier fixed-environment platforms share the same structural gap: without variation across episodes, they cannot distinguish an agent that has learned generalizable behavior from one that has memorized a fixed sequence. That's a real limitation on what ALE results can tell you, however useful the platform has been for other purposes. Procgen's design choices went on to shape later benchmarks, including C-Procgen and Craftax, and helped push generalization, architecture scalability, and reproducibility into the center of RL research rather than the periphery.
The "SFT memorizes, RL generalizes" finding and its contribution to the evaluation picture
Chu et al.'s "SFT Memorizes, RL Generalizes: A Comparative Study of Foundation Model Post-training" (ICML 2025, pp. 10818-10838) takes this same question and applies it one level up, to how foundation models are post-trained rather than to game-playing agents. The paper introduces GeneralPoints, an arithmetic reasoning card game, and pairs it with V-IRL, a real-world navigation task, to test whether models generalize to rule variants they weren't trained on, both in text and in vision.
The result lines up with everything above: RL trained with outcome-based reward generalizes across textual and visual rule changes the model never saw during training. Supervised fine-tuning, by contrast, memorizes the training data closely and fails to generalize to unseen rules or out-of-distribution scenarios. RL training in this study appears to improve the model's underlying visual recognition ability, not just its task-level score, suggesting the advantage sits deeper than policy adaptation alone. None of this makes SFT dispensable. SFT still plays a role in the broader training pipeline, so the two methods function as stages more than as rivals.
A follow-up critique complicates the clean version of this story, and it deserves equal weight rather than a footnote. When researchers track out-of-distribution performance across the entire SFT training trajectory rather than at one snapshot, there are checkpoints where SFT models outperform RL fine-tuned models. The "SFT memorizes, RL generalizes" framing holds at some points in training and not others. The conclusion is sensitive to exactly which checkpoint gets compared to which. This is the same evaluation issue the rest of this piece has been describing, just relocated. Even a well-built comparison, clear task, held-out variants, two methods, still depends on protocol choices, which checkpoint, which point in the trajectory, which variant distribution, that can flip the finding.
Three categories of methods that address the generalization gap
Kirk et al. (2023, JAIR 76:201-264) survey the field and sort proposed fixes into three groups, each resting on a different assumption about what evaluation is supposed to catch.
Increasing train/test similarity covers data augmentation and synthetic environment generation, on the theory that if training data is diverse enough, the test distribution stops being unfamiliar. RAD and DrQ, which apply random image crops or pixel shifts, meaningfully improve data efficiency and training stability for Q-learning, even in settings where train and test environments are identical. Not every augmentation helps, though: rotation, random convolution, and masking have been shown to destabilize training and hurt data efficiency, so augmentation choices need validation against the specific protocol being used, not just applied by default. Domain randomization, a broader version of the same idea, helps prevent memorization but is sample-inefficient and can never enumerate every variation a real deployment might throw at an agent.
Modeling distributional discrepancies directly takes a different approach: build a model of how training and test environments differ, and train a policy that can adapt to that difference rather than pretending it doesn't exist. Model-based RL, using a learned world model instead of pure value functions or replay buffers, tends to generalize better to unseen environments. IMAC is a concrete example: it trains a diffusion-based world model from offline data, then uses Prioritized Level Replay and Unsupervised Environment Design to build what amounts to an imagined curriculum, selecting generated worlds that maximize the agent's regret so training stays at the edge of its current competence. Agents trained inside this imagined world model have shown transfer to environments they never saw directly.
Structural modifications to the RL algorithm itself make up the third category. Decoupling policy and value networks, rather than sharing parameters between them, is one structural modification proposed to improve generalization. Other work in this category revisits exploration strategies and fast-adaptation methods. One notable approach predicts an agent's generalization score directly from its internal weights, without running it on any test environment, and feeds that prediction into the PPO loss function during training. Agents trained with this modified PPO showed stronger generalization than standard PPO on both CoinRun and Minigrid.
Each category smuggles in an assumption. The assumption behind Type 1 is that augmented training data can stand in for the real test distribution. Type 2 assumes the learned world model is accurate enough that imagined experience actually transfers to reality. Type 3 assumes the architecture or training signal correctly flags overfitting before test performance ever measures it. Kirk et al. also flag a limit on procedural benchmarks generally: they don't push research toward fast online adaptation, offline RL's zero-shot generalization problem, or reward-function variation, which is exactly where real deployments diverge most from procedurally generated test suites. Memorization-aware training, a separate technique, uses held-out prediction error as a signal during training to shift a model's logits toward more invariant features. It comes from supervised learning, but the logic maps onto the problem of evaluating RL almost without modification.
What good evaluation protocol design requires
Everything above points to one requirement, and it's a strict one: an evaluation protocol has to be capable of producing a gap between training performance and test performance. If a protocol structurally cannot produce that gap, because train and test are the same set of environments, it cannot tell memorization from generalization, full stop. That's not a limitation to work around; it's a disqualifying property.
Separating training and test environments has to happen at the structural level. Procedural generation with genuinely held-out seeds is the floor, not a nice-to-have. Reusing the same environment set and calling it evaluation, still standard practice in parts of the field, doesn't clear that floor.
Good protocols also test for reliance on the wrong cues. The Sonic timer result matters here beyond its own experiment: removing a spurious feature that happens to correlate with reward is often the only way to find out if an agent learned the task or learned the correlation. Evaluation designed without that kind of manipulation will miss the failure mode.
Finally, a serious protocol tests at more than one level of distributional shift, because generalization failures look different depending on what's varying. Procgen's seed-based randomization tests visual variation: different textures and colors over the same dynamics. CoinRun's procedural levels test layout variation. Chu et al.'s GeneralPoints and V-IRL setup tests something harder still, variation in the rules and dynamics themselves. None of these three substitutes for the others. A benchmark that only varies visuals will never catch an agent that's overfit to layout, and a benchmark that only varies layout will never catch one that's overfit to rules it never had to question. Evaluation design isn't a formality that comes after the interesting research. It decides whether the research is measuring what it claims to measure.