Expected Calibration Error Limitations in Modern ML
Confidence scores don't mean what deep networks claim they mean.
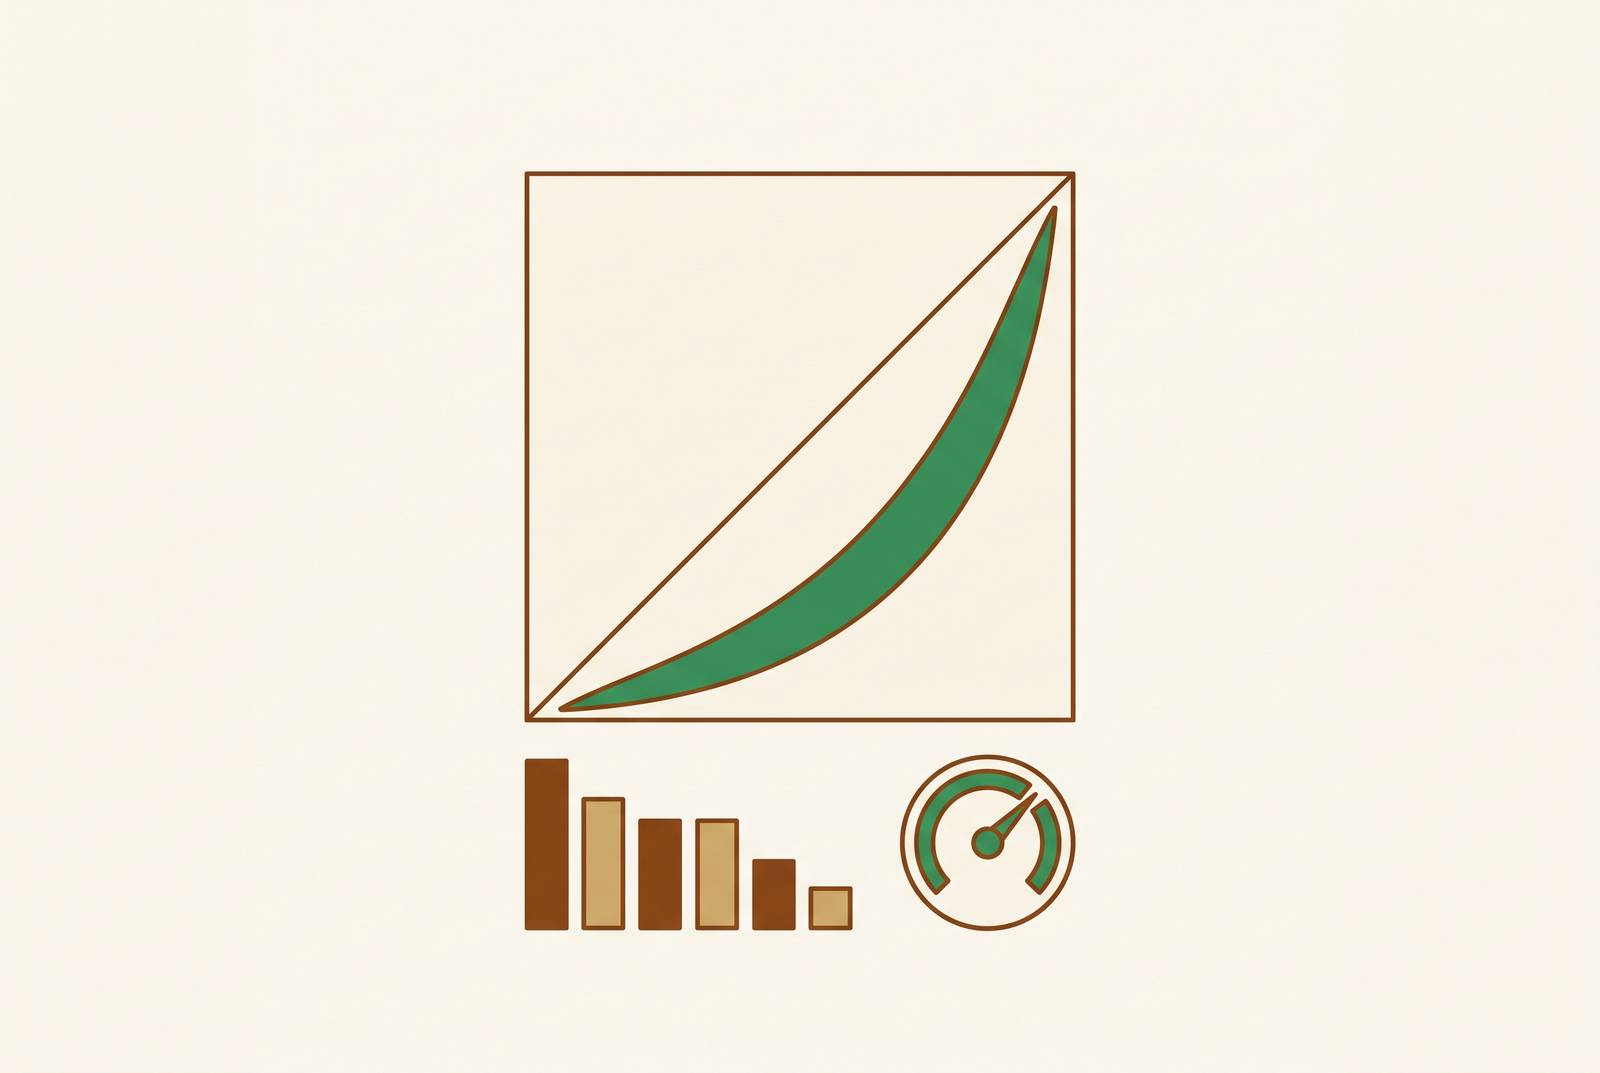
A model can get every prediction right in aggregate and still lie to you about how sure it is. That gap, between accuracy and honesty about confidence, is what calibration is built to measure, and it has nothing to do with how often the model is correct. A classifier that nails the right answer most of the time isn't automatically well-calibrated. Calibration asks a narrower question: does the confidence number attached to each prediction mean what it claims to mean?
Take a diagnostic tool that flags a tumor as malignant with 70% confidence. If that number is honest, then out of a hundred patients who get that exact score, about seventy should actually have the malignancy. If only forty do, the model isn't wrong about the diagnosis so much as wrong about its own certainty, and in medicine that gap separates a tool doctors can lean on from one that quietly misleads them.
Deep networks are bad at this in a specific, well-documented way. Guo and colleagues traced the problem to how cross-entropy training behaves once a network has basically solved the classification task: negative log-likelihood keeps falling long after classification error has flattened out, because the model can keep lowering the loss just by pushing predicted probabilities closer to 0 and 1. Past that point, the network is learning to sound more certain, not to be more correct, and confidence quietly comes apart from accuracy.
The architecture choices that got deep learning to where it is now make this worse, not better. Guo et al. found that added depth, added width, and batch normalization all push ECE up, while proper weight decay pulls it back down. That's a strange trade, since the exact levers researchers pull to improve accuracy are, in several cases, the same levers that degrade the honesty of the model's confidence scores. Anyone chasing state-of-the-art accuracy numbers without checking calibration afterward is very likely making the confidence scores worse on the way there.
ECE Computation and Design Choices Entering Before a Single Result Is Reported
Expected Calibration Error sounds like a fixed, objective quantity. It isn't, because the standard recipe splits the interval from 0 to 1 into M bins, drops every prediction into a bin based on its confidence score, then in each bin compares the average confidence to the actual fraction correct. The standard recipe splits the interval from 0 to 1 into M bins, drops every prediction into a bin based on its confidence score, then in each bin compares the average confidence to the actual fraction correct. Multiply that gap by how many predictions landed in the bin, then sum across all bins to get ECE.
Every step in that recipe hides a choice, and none of the choices are neutral. The number of bins, M, has no fixed standard. Papers commonly use something between 10 and 15, a range that reflects convention more than principle, and swapping M can shift the reported number meaningfully on the same model and the same test set.
Then there's the top-1 convention. In a multiclass setting, a model doesn't output one number, it outputs a full distribution over every possible class. Standard ECE throws almost all of that away and keeps only the highest softmax value, the model's confidence in its single top guess. Whatever the model believed about the other classes never enters the calculation.
Finally, there's how the bins themselves get built. Most implementations default to equal-width bins, dividing 0 to 1 into evenly sized slices without regard to how many predictions actually land in each one. That sounds like the neutral choice. It is, in fact, the opposite, and it turns out to be one of ECE's deepest structural problems.
The binning instability problem and its bias-variance consequences
Binning forces a trade-off with no clean resolution. Fewer bins mean each bin holds more samples, so the accuracy estimate inside it is statistically more stable, but coarser bins blur together predictions that might have genuinely different calibration behavior, and that blur is bias. Pushing toward more bins shrinks the bias, but individual bins now hold fewer samples, and the accuracy estimate inside each one gets noisy. No bin count escapes both problems at once.
Modern networks make this worse in a specific way, tied to how they distribute their confidence scores. A well-trained deep model, especially after the overconfidence effect Guo et al. documented, tends to cluster its predictions up near the high end of the scale. Most of the probability mass in an equal-width binning scheme piles into the last one or two bins, while bins covering the lower-to-middle range sit nearly empty. Since ECE weights each bin's contribution by how many samples landed inside it, those near-empty low-confidence bins contribute almost nothing to the final number. The metric ends up summarizing calibration behavior over a narrow slice of the probability range, while pretending that slice speaks for the whole space.
There's a further wrinkle: ECE isn't smooth. A small tweak to model outputs, say from a minor change in training or a slightly different checkpoint, can nudge a batch of predictions just enough to cross a bin boundary. That shifts which bin absorbs them and can move the reported ECE by a large jump for what was a genuinely tiny underlying change. A cost that arises when predictions cluster tightly is most visible then, since a lot of mass can cross the same boundary at once.
None of this is a bug that better engineering fixes. Binned ECE, under any binning scheme, is a biased estimator of the true calibration error of the underlying model. That's a property of the estimator itself, not an artifact of sloppy implementation, and no amount of careful bin-tuning changes what the estimator fundamentally is.
The fundamental estimability problem: why no binning fix can fully solve this
A deeper issue sits below binning. The population quantity ECE is trying to approximate, sometimes written as ℓ₂-ECE, cannot be estimated with any accuracy guarantee in a fully assumption-free setting. That's an established theoretical result about what's mathematically possible to recover from finite samples.
"Assumption-free" is doing real work in that sentence. Without imposing some regularity condition on the true conditional accuracy function, something like smoothness or bounded total variation, no estimator, binned or otherwise, comes with a guarantee of converging to the right answer as sample size grows. The function mapping predicted confidence to true accuracy could in principle be so jagged that no amount of data pins it down reliably.
Every calibration tool used in practice, including every binned ECE variant, sidesteps this by quietly assuming enough smoothness to make estimation tractable. Binning gets used because it's the only workable compromise once the exact quantity is acknowledged to be out of reach, not because it's a particularly good compromise.
That hardness result reframes what a reported ECE number actually is. It is an estimate whose reliability rests on assumptions the practitioner rarely states out loud. It's an estimate whose reliability rests on assumptions the practitioner rarely states out loud, and that dependency doesn't go away no matter how the bins are drawn.
The testability-actionability tension that ECE falls on the wrong side of
Rossellini, Soloff, Barber, Ren, and Willett laid out two properties any calibration measure should ideally have (COLT 2025, PMLR 291:4937 to 4972). Testability means the measure can actually be estimated reliably from a finite sample. Actionability means a small value of the measure gives a genuine, decision-theoretic guarantee about how the model can be trusted downstream.
ECE was built for actionability, not testability, and that's the choice that eventually catches up with it. The entire point of asking whether a 70% prediction is correct 70% of the time is to license a downstream decision, treating that confidence score as a usable probability. But ECE cannot reliably be estimated, for the reasons above, so it fails the testability side of the ledger: in many practical settings, it simply cannot be pinned down from the data at hand.
Distance from Calibration, dCE, sits in the opposite corner. It can be estimated reliably from finite samples, but it doesn't carry the same decision-theoretic guarantees ECE promises, so a low dCE doesn't tell a practitioner much about whether they can safely act on the model's stated confidence.
Cutoff Calibration Error, introduced in the same body of work, tries to occupy the corner neither ECE nor dCE reaches: testable and actionable at once, by assessing calibration over intervals of forecasted probability rather than either fixed narrow bins or a single global distance. Its behavior has been examined specifically for isotonic regression and Platt scaling, two of the most common post-hoc calibration methods in use, and the result is evidence that the tension can be avoided. It's unresolved by ECE specifically, which is a different claim.
ECE Blind Spots: Sharpness, Sign of Miscalibration, and Group-Level Disparities
A model can post a low ECE while being nearly useless, and this is where ECE's reputation as a trustworthy default falls apart fastest. ECE measures calibration alone, not sharpness (sometimes called refinement), which is the model's ability to actually discriminate between classes with confidence spread across the range rather than clustered at some safe middling value. The point follows directly from ECE's construction: a model that outputs something close to the base rate for every single input can look well-calibrated by ECE's math while telling a practitioner nothing useful about any individual case.
Standard ECE also can't tell you which direction a model is wrong in. Overconfidence and underconfidence cancel out inside the same aggregate number, since ECE takes an absolute difference between confidence and accuracy. Two models with wildly different failure modes, one that systematically overstates its certainty and one that understates it, can report identical ECE. Variants designed to recover that sign information exist, but it's absent from the metric most papers actually report. Most papers are reporting a number that hides the one detail a practitioner would most want to know.
The top-1 convention compounds this. By keeping only the maximum softmax value and discarding the rest of the predictive distribution, classic ECE understates miscalibration in any multiclass setting where the shape of the full distribution matters. It's simply the wrong tool for tasks that need distributional calibration, such as token-level language modeling, where the object of interest isn't one scalar confidence but the full predictive distribution across outputs.
ECE has an aggregation problem on top of all this. It bins by confidence level, not by subgroup or input characteristic, so a model can be well-calibrated on average across an entire test set while being badly miscalibrated for a specific demographic slice or input category. Global ECE cannot register that kind of disparity, because subgroup-level errors are collapsed into aggregate bins with no subgroup labeling. Global ECE has no visibility into that kind of disparity by construction, and treating a low global ECE as a fairness guarantee is a mistake baked into the metric itself.
How ECE's limitations compound in LLM evaluation
Large language models sit at the exact intersection of ECE's two blind spots. Token-level and sequence-level calibration in an LLM involve a probability distribution spread across a vocabulary of tens of thousands of tokens. ECE's top-1 convention throws away almost the entire distribution the moment it collapses everything down to the single highest-probability token.
Sequence-level uncertainty compounds the problem further. Asking a model to state its own confidence in words, "I'm 80% sure," produces numbers that are systematically biased and correlate poorly with whether the answer is actually correct. A more reliable signal is thought to be answer consistency across repeated samples from the model, rather than anything the model says about itself. Running ECE on verbalized confidence scores, then, measures something closer to the model's rhetorical habits than its actual reliability, and treating that number as a calibration score is close to measuring the wrong thing.
Recent work on LLM calibration also describes a split between calibratable and non-calibratable regimes based on how far fine-tuning has progressed. In the calibratable regime, calibration-aware fine-tuning can bring a model's confidence scores closer in line with its accuracy. Push further into fine-tuning aimed purely at task performance, though, and models can cross into a regime where ECE-based recalibration stops working, no matter how it's applied.
Llama-3.1-Tulu-8B, Vicuna-7B-v1.5, OLMo 2-7B, and Mistral-7B have all been documented in recent calibration research as exhibiting notably poor calibration after alignment. The pattern is a reminder that the same training steps designed to make a model more helpful and more aligned with human preference can push its confidence scores further from reality, not closer.
Post-hoc calibration methods' interaction with ECE's distortions
The standard fix for a miscalibrated model is post-hoc calibration: hold out a validation set, fit a simple correction, apply it at inference time. That correction is only as good as the validation data behind it. If the validation set doesn't represent the conditions the model will actually see in deployment, the correction can't generalize, and a post-hoc method's limited capacity to model complex calibration maps means it can only stretch so far under domain shift.
The intuitive story is just wrong here. The standard assumption in calibration research has been that distribution shift makes overconfidence worse. On standard ImageNet-style benchmarks, though, current-generation pretrained models have been observed to run underconfident rather than overconfident on standard benchmarks, and ECE can in some cases improve rather than degrade under such conditions. Practitioners who assume shift always erodes calibration are working from a rule that doesn't hold, and they need to check the direction of the effect rather than assume it.
On in-distribution data, a single temperature parameter, one scalar that rescales the logits before the softmax, is often enough to fix most of the calibration error. But that same fix, tuned on in-distribution validation data, can raise ECE above the uncalibrated baseline when applied blindly under severe distribution shift. The correction that helps at home can actively hurt once the input distribution moves, and there's no way to know which outcome you'll get without testing under the actual shift you expect to see.
Temperature scaling's evaluation is itself tangled up with the binning bias described earlier. Because the relationship between accuracy and ECE can be positive or negative depending on how many bins the evaluator picks, a post-hoc calibrated model can appear better or worse purely as a function of the evaluator's bin count, with nothing about the model itself having changed. The metric and the method it's supposed to validate end up entangled in a way the reported number never reveals.
Alternatives that address specific ECE failure modes
Equal-mass, or adaptive, binning is the most direct patch to binning bias, and it should probably be the default rather than the alternative. Instead of dividing the 0 to 1 range into evenly spaced slices, equal-mass binning builds bins that each contain the same number of samples, which keeps the accuracy estimate inside every bin comparably stable. Researchers have recommended against equal-width binning on these grounds and proposed equal-mass alternatives designed to reduce the sensitivity of the reported number to sparse bins. Equal-mass variants are generally argued to reduce the bias introduced by uneven bin occupancy compared to equal-width versions.
ECE-DEBIAS goes a step further by correcting the bias directly rather than avoiding it through smarter bin construction. It applies a jackknife technique to estimate the per-bin bias in standard ECE and subtracts that estimate out. Comparative analyses of these estimators suggest meaningful differences in bias across variants, though the ordering depends on the evaluation setting.
SmoothECE takes a different approach and drops bins. It replaces hard bin boundaries with kernel smoothing, typically a reflected Gaussian (RBF) kernel, producing a continuous calibration error estimate that sidesteps the bin-boundary artifacts and discontinuous jumps described earlier, while staying provably consistent with the true calibration distance as sample size grows. Related methods, Maximum Mean Calibration Error and Kernel Calibration Error, use RKHS embeddings of the calibration residual to get at a similar goal from a different mathematical angle.
rankECE, from Chatterjee and Barber, tackles estimability head-on instead of working around it. Rather than binning at all, it compares each prediction against others with similar predicted probability values, ranked by proximity, and that gives it theoretical guarantees closer to the true population ECE than any binned approximation can offer. None of these alternatives make ECE's underlying assumption-dependence disappear. Each one closes off a specific, well-documented failure mode, though, and together they add up to a serious body of corrective work aimed at a metric that, in its standard textbook form, does not hold up under close inspection.
Sources
- A Ranking Approach for Measuring Calibration
- Calibration in Deep Learning: A Survey of the State-of-the-Art
- Understanding Model Calibration - A gentle introduction and visual exploration of calibration and the expected calibration error (ECE) | ICLR Blogposts 2025
- A Confidence Interval for the $\ell_2$ Expected Calibration Error
- On calibration of modern neural networks | Proceedings of the 34th International Conference on Machine Learning - Volume 70
- Reassessing how to compare and improve the calibration of machine learning models | NSF Public Access Repository
- arxiv.org
- arxiv.org